PrismML aims to transform our AI interactions with its compact LLM.
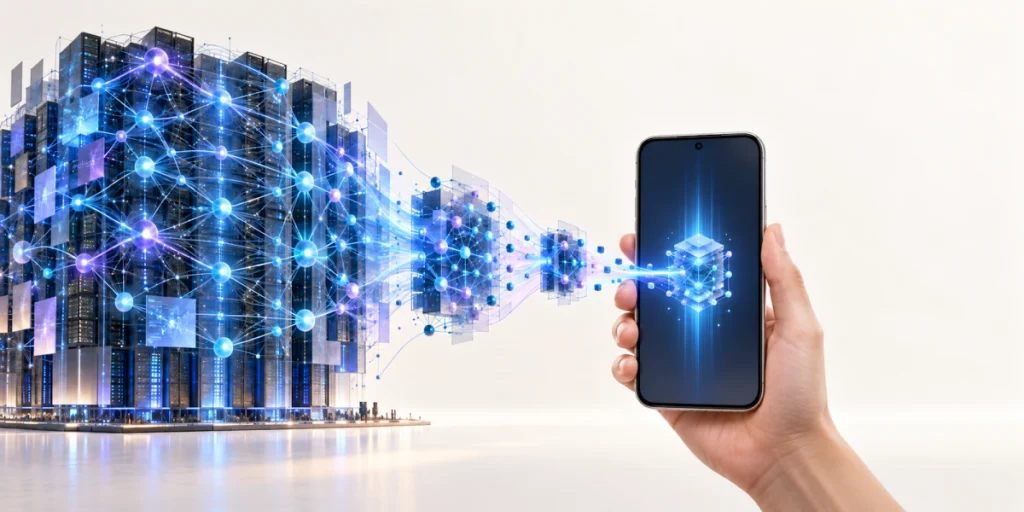
Image Credits:TechCrunch, AI generated
Why PrismML Deserves Your Attention
If PrismML isn’t on your radar yet, it should be. The AI startup has drawn attention not by raising a massive amount of funding—its reported $22.25 million seed round is modest compared to other tech ventures—but rather due to the caliber of its team and the innovative technology it is developing. With a focus on artificial intelligence, PrismML is betting on the promising idea that effective, reasoning large language models (LLMs) can exist in a compact form, challenging conventional notions of model size and performance.
Compact Yet Powerful Models
PrismML is pioneering models that are small enough to run on personal computers and smartphones. There are even whispers of potential collaborations with major tech companies like Apple, although CEO Babak Hassibi has refrained from confirming this to TechCrunch.
Recently, PrismML introduced Bonsai 2 27B, the latest iteration in its family of models. This model compresses the widely utilized Qwen3.8 27B, a model created by Alibaba, reducing its size to a mere 5.9 GB—small enough to fit seamlessly on both PCs and high-end smartphones. This represents a 9x to 10x reduction in memory compared to the original.
PrismML was founded by a group of researchers from Caltech, under the leadership of Hassibi, an expert in compression technologies. The startup has also enlisted Ion Stoica as an adviser; Stoica is well-known as a co-founder of Databricks and director of Berkeley’s esteemed Sky Computing Lab, a hub for groundbreaking technologies and startups.
Backed by prominent investors including Khosla Ventures, Cerberus Capital, and Caltech, PrismML finds itself in a competitive landscape of LLM compression technologies. Other notable companies like Multiverse Computing are also making strides in this field, though they have attracted significantly more funding.
High Performance with Low Footprint
What sets PrismML apart, according to Hassibi, is its unique compression technology that maintains performance integrity. Bonsai 2 achieves an impressive 98% match with Qwen’s aggregate benchmark scores—a notable improvement from its predecessor, which only reached 95%. In just a couple of months, the original Bonsai model has been downloaded over 11 million times, while the smaller variant has accumulated an additional 2.6 million downloads.
The question of whether PrismML can achieve 100% benchmark performance remains open, but the company has shown consistent improvement in its compression results over successive releases. Even though some degradation is likely with any compression, Hassibi points out that a 2% loss in performance may not significantly impact the model’s real-world effectiveness, given the inherent inaccuracies of uncompressed LLMs and the differences in task execution.
The Science Behind Compression
PrismML’s groundbreaking approach involves reducing the size of the “weights” in a model. Weights represent the information that models learn and store during training. Traditionally, each weight is stored as a 16-bit value, but PrismML employs a technique called “ternary” weights, which simplifies this to three states: +1, -1, or 0. This innovative reduction in data storage results in far less memory usage for the model without sacrificing performance.
For those interested in a deeper exploration of the compression technique, more information can be found on the project’s Hugging Face page.
Future Aspirations for Larger Models
Looking ahead, PrismML aims to apply its compression technique to even larger models. Hassibi anticipates releasing models in the several-hundred-billion-parameter range within the next few months, and he suggests that maintaining the intelligence of these larger models will be more manageable. As the models increase in size, there is greater potential for compression without sacrificing their cognitive capabilities.
Stoica echoes this sentiment, expressing enthusiasm for a future where sophisticated AI models can run directly on user devices. “You are going to have intelligence at your fingertips, and it’s going to be free because it’s going to run on the device you already own. It’s also going to be private, as you won’t have to send your data to the cloud,” he explains.
The Implications of Compact AI
The significance of PrismML’s advancements extends beyond merely enhancing performance metrics. The ability to run powerful AI models locally on devices could reshape how we interact with technology. It could lead to far-reaching implications for privacy, accessibility, and even the democratization of advanced AI features across a broader segment of the population.
The shift toward smaller, high-performing models could also catalyze an era of innovation, enabling developers to create applications that leverage AI capabilities without necessitating extensive cloud infrastructure or high-performance computing resources.
As PrismML continues to evolve and refine its technology, the potential for transformative changes in the industry is immense. By making AI more accessible, efficient, and private, PrismML stands to carve out a significant niche in the rapidly growing AI landscape.
Conclusion
In summary, PrismML represents a compelling case for the future of artificial intelligence. By challenging the prevailing belief that larger models are inherently superior, this startup is not only pushing the boundaries of what is technically possible but also redefining the fundamental approach to AI deployment. With its innovative compression technologies, impressive early performance, and focus on making AI accessible to everyday devices, PrismML is undeniably a name to watch in the coming years.
Thanks for reading. Please let us know your thoughts and ideas in the comment section down below.
Source link
#PrismML #hopes #tiny #LLM #change
About The Author